24 October 2026
Prefill and decode on CPU, GPU and NPU
Every pairing of the three processors on a Snapdragon 8 Elite Gen 5, for nine models in one llama.cpp build, on real multi-turn conversations.
 OpenWeightsOn Google Play
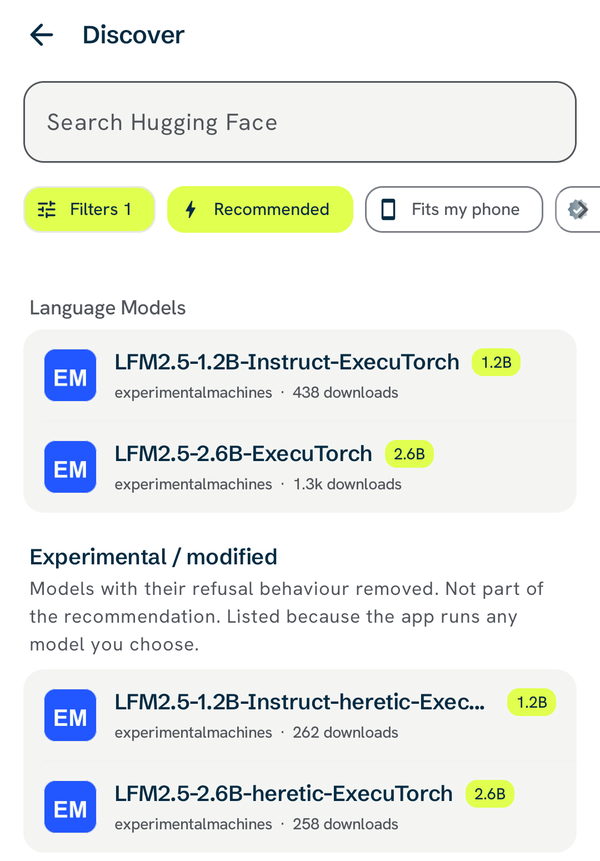
OpenWeights searches Hugging Face for GGUF and ExecuTorch models, estimates whether one fits your phone before you download it, and runs it on the device. Every token comes from your own hardware: no account, no cloud, no telemetry.
24 October 2026
Every pairing of the three processors on a Snapdragon 8 Elite Gen 5, for nine models in one llama.cpp build, on real multi-turn conversations.
7 September 2026
Does the exported window matter?
ExecuTorch fixes a model's context window when the model is exported, from 2k to 32k. Whether that choice changes anything but memory.
7 September 2026
A second pass over the window matrix: every cell checked for a failed or noisy run, and three things rerun the same day.
3 and 4 September 2026
Median time to first token and time per output token for five small models on five phone chips, in llama.cpp and ExecuTorch.
Apache-2.0, on GitHub. Android 12 or later on arm64; an iPhone version is experimental. Models are published by third parties and their licences are their own.